AI can do the work that used to need a person.
For decades, a whole category of business problems had no good answer. Not because nobody tried, but because the work required judgment about messy human input, and software could only follow rules. That changed. We build the systems that take advantage of it, and we spend our days testing new models to find out which ones can be trusted with the job. And if AI isn’t the right tool for your problem, we’ll tell you that too.
AI changed which problems are worth solving.
The constraint for a business was never what was technically possible somewhere. It was whether the fix cost less than the problem.
Software could only follow rules you wrote down
If you could specify every case in advance, it could be automated. If the work needed judgment about input that arrived in whatever shape a human felt like sending it, you hired a person. There was no third option, no matter how big your budget was.
Models handle input nobody standardized
A model reads a document it has never seen the layout of, follows a phone conversation that goes sideways, and understands that "3/8 hex cap, gr8" and "Grade 8 hex cap screw 0.375" are the same part. None of that reduces to rules, which is exactly why it stayed manual.
The build got cheap enough to be worth it
The same shift cut what it costs to build software at all. Problems that needed a contract team and a year of rollout now take weeks. Plenty of work that was never worth automating at a 12-person company suddenly is.
Six problems that had no good answer before this.
Every one of these is somewhere in a business right now, being done by hand because there was never another option.
Every one of them needs judgment before a rule can apply
Somebody has to read it, hear it, or interpret it first. That first step was the blocker. Once a machine can do it reliably, the rest of the work was always straightforward automation, and often was already automated everywhere except that first step.
Documents nobody standardized
Invoices, RFQs, remittances, lab results, statements. The old approach was OCR plus a hand-built template for each layout, which broke the day a vendor redesigned their form. A model reads a layout it has never seen, the way a new hire would.
IN PRODUCTION: EAGLE MEDICAL BILLINGUnderstanding a phone call
For thirty years the state of the art was press 1 for sales. Nobody could build a phone system that understood a caller, asked a sensible follow-up, and wrote down what was said. That is now routine to build.
IN PRODUCTION: INTEGRATED CLINIXMaking sense of free text
Emails, notes, complaints, work requests. Keyword rules caught the phrasing you thought of and missed everything else, so somebody read every message and sorted it by hand. Sorting, summarizing, and identifying the request is now reliable.
EMAIL · TICKETS · INTAKERecords that mean the same thing
The same customer, part, or vendor written four ways across four systems. Matching them was a genuine research problem, so instead a person reconciled spreadsheets every month and the duplicates never fully went away.
DEDUPLICATION · RECONCILIATIONHandwriting and photos from the field
Job tickets, meter readings, delivery slips, inspection notes, all photographed on a phone in bad light and then typed in by someone at a desk that evening. That transcription step no longer needs a person.
FIELD CAPTURE · JOB TICKETSDeciding what happens next
Routing, prioritizing, and flagging the exception that needs a human. Rules engines could do this only if somebody maintained the rules forever, and nobody ever did. Judgment about what matters is exactly what changed.
ROUTING · TRIAGE · ESCALATIONWe spend our days testing new AI models so you never have to think about them.
New models ship constantly. Which one is right for your job changes every few months, and the difference lands on your bill and in your error rate.
Every time a new model lands, the coverage is about benchmark scores. Benchmarks do not tell you whether it can read your vendor's invoice layout, hold a phone conversation that goes off script, or classify your RFQs without quietly inventing a part number. So we test against real workloads instead, using your own documents and your own calls, and above all the edge cases that broke whatever we were using before.
That testing is the unglamorous part of this work and it is most of the value. Model choice is not a decision you make once. A system shipped a year ago may be running on a model that now costs several times more than a newer one that does the job better, and the reverse happens just as often, where the cheap model everyone recommends turns out to be the one that fails on your hardest 5% of documents. We re-run our evaluations when something new ships and only migrate clients when the numbers justify it.
The practical result is that different jobs in the same system run on different models. A small fast model classifies incoming email for a fraction of a cent. A frontier model handles the reasoning that has to be right. Anything touching data that cannot leave your environment runs locally on hardware you control. You should never have to know which is which, and you should never be paying frontier prices for a job a cheap model does better.
WE TEST FOR Your documents, your calls, your volume
- Accuracy on the edge cases that broke whatever you were using before
- Cost per run at your real volume, projected over a year
- Latency, because a voice agent that thinks for four seconds has already lost the caller
- Failure behaviour: does it say it doesn't know, or does it confidently make something up
- Whether it can run locally when the data can't leave your environment
WE IGNORE What doesn't
- Leaderboard rankings and benchmark headlines
- Launch-day claims from whoever built the model
- Whichever model everyone is talking about this month
- Sticking with a vendor because we already integrated it
The parts we won't hand to a model.
AI is one component inside a larger system. Deciding where it does not belong matters as much as deciding where it does.
Anything that has to be exactly right
Totals, tax, margin, payroll, quantities. The arithmetic and the checking are done in code. A model may read the number off a page, but it never decides what the number is, and every extraction is checked against the records you already have.
Data that can't leave your environment
We decide where your data is allowed to travel before we design anything else. When information is too sensitive for an external service, parsing runs locally and nothing is sent out. We do this today for HIPAA-regulated medical billing data, with role-based access, encryption, and audit logging.
Decisions with consequences and no human nearby
A model can draft, flag, sort, and prepare. Releasing a payment, sending something legal, or committing to a customer goes to a person. The system's job is to make that person's decision take thirty seconds instead of an hour.
Straight answers
Is this just ChatGPT with your logo on it?
No. A chat window is a product you can already buy for $20 a month, and if that solves your problem we will tell you to go do that. What we build is a system that sits inside your process. It receives the document or the call, does something specific with it, checks the result against your records, writes it to the place your team actually works, and escalates when it isn't sure. The model is one component inside that, usually a small one.
Which models do you use?
Whichever one wins on your workload, and usually several within one system. We test the current frontier models from the major providers plus the open models that can run on hardware you control, and we pick per job rather than per client. Classification, extraction, conversation, and reasoning have genuinely different winners, and they change.
What happens when a better model comes out?
We re-run our evaluations against your real workload and tell you what we found. If a change is worth making, we make it, and in a well-built system that is a configuration change rather than a rebuild. If the new model is worse for your job, which happens more often than the coverage suggests, we leave it alone and say so.
Will it make things up?
A model on its own will, occasionally, which is exactly why the architecture around it matters more than the model. Extractions get validated against records you already have. Numbers that have to be right are calculated in code. Anything the system isn't confident about gets flagged to a person rather than guessed at. We would rather build something that escalates too often at first and gets tuned down than something that quietly gets a claim wrong.
Is my data used to train anyone's model?
Not on the configurations we deploy. Business API tiers from the major providers do not train on submitted data by default, and we confirm that per provider rather than assuming it. When the data is sensitive enough that the question shouldn't depend on a vendor's policy at all, we run the processing locally so nothing leaves your environment. That is what we did for HIPAA-regulated claim data.
Do I need to understand any of this to work with you?
No. You need to know which parts of your week are eaten by someone reading, typing, or interpreting something. We work out whether a machine can do it reliably, what it costs to run, and whether the savings justify the build. If they don't, we'll tell you that on the first call.
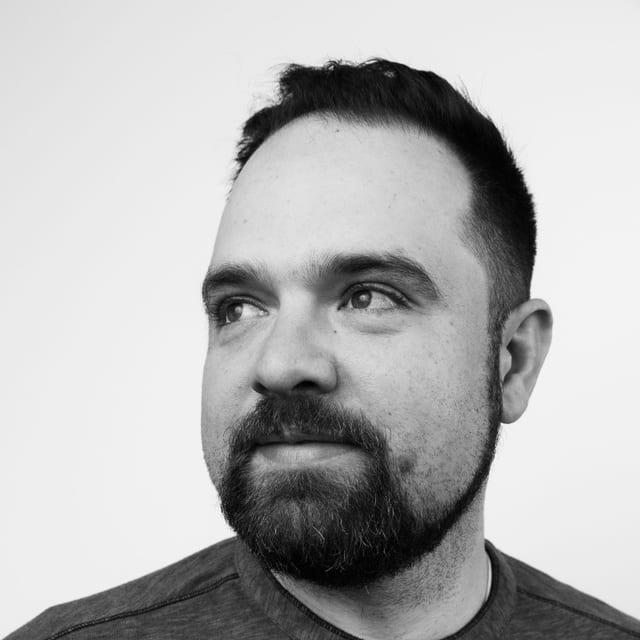 Malcolm
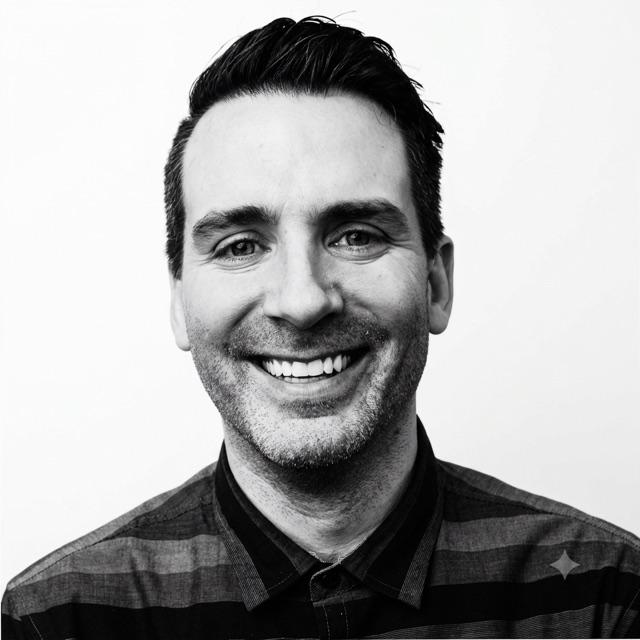 Michael
We’d love to work with you
Have a chat with Malcolm and Michael about the work that needs someone to read or judge something first, and whether AI can do it reliably.
Get in Touch →Or email us directly: hello@hellospark.ai